Tractatus
Figuring out what intelligence actually requires. ARC-AGI-3 is the test I measure against; below is what the loop has done so far, with receipts.
Tractatus says only what is the case, and shows the receipt.
The hardest test of fresh-environment reasoning. Every frontier LLM scored under 1% on it at launch. GPT-6 Astra reaches 99.9% with the Provider Adapter harness ($18,817 a run) and 62.7% with ARC Prize's standard one. The harness moved it 37 points, and the harness is what I build.
My first system (August) cleared all 183 public levels, but only because I tuned it on those games. On unseen games it scored almost nothing, so now test games stay held out. GPT-6 Astra inside my general loop, with no game-specific content, has since cleared them all: 183 of 183, all 25 games, every run replayed move for move.
Inside my harness the same Astra clears ar25 8/8 cold at 7,704 output tokens. Before the slicing, inside my general loop, it needed 35,842. The harness does the thinking; the model only picks from what the harness offers, and every decision leaves a receipt. An open 125B model in the same seat has now cleared four full games cold, every run replayed step by step by a separate verifier. The player contains no game-specific content.
As of 26 Sep, next: the remaining public games on one frozen version, then the five reserved games, then the hidden set on Kaggle with the open model offline on one GPU.
Qwen3.8-Flash picking, cold from RESET, version 0916ai. The frames are the run's own observation log, not a replay. The counter shows how many picks the model had made.
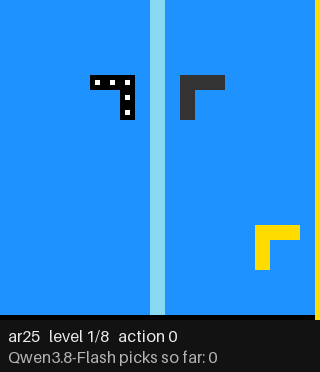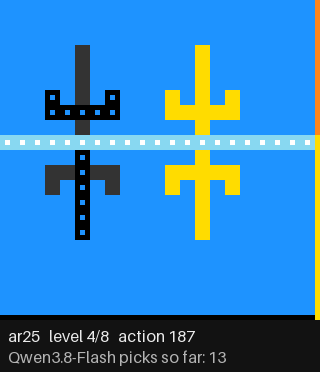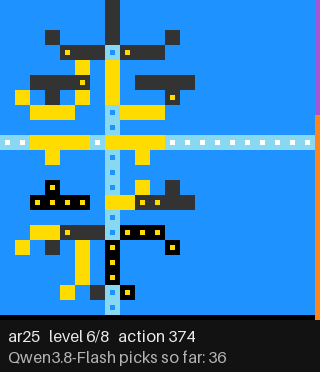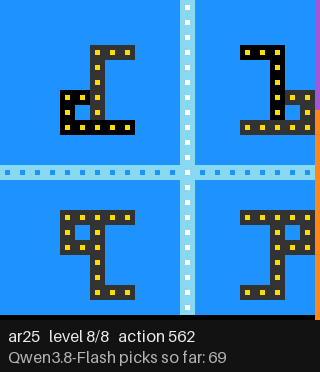
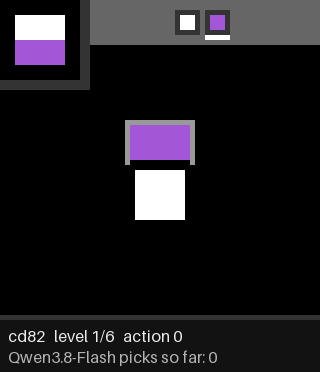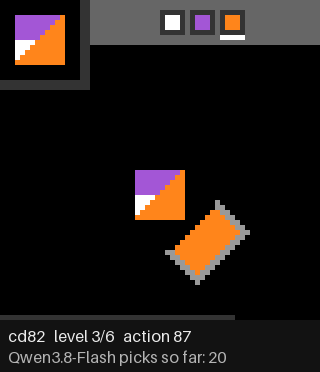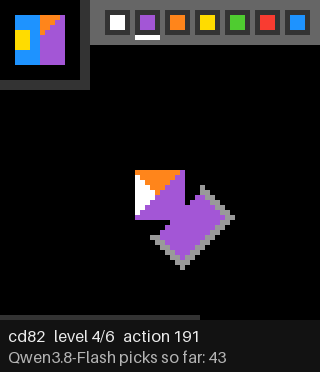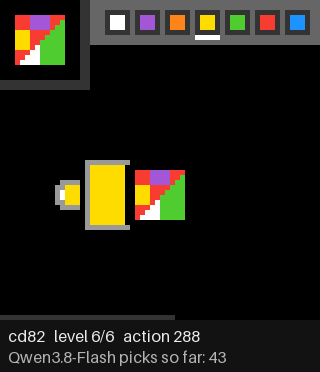
Same loop, different seats. Output tokens are the model's, reasoning included. Every observation in the Tractatus rows was replayed exactly, and every forecast was scored against what happened.
| Run | Result | Calls | Output tokens | Note |
|---|---|---|---|---|
| GPT-6 Astra, ARC Prize's verified run, Provider Adapter harness | 99.9% semi-private | — | — | $18,817 for 55 games |
| GPT-6 Astra inside my loop, unsliced | ar25 8/8 | — | 35,842 | All 25 public games cleared, 183 of 183 levels; no game-specific content |
| GPT-6 Astra inside Tractatus, mostly picks | ar25 8/8 cold | 93 | 7,704 | 604 observations and 257 forecasts replayed |
| Open 125B model (Qwen3.8-Flash) inside Tractatus, mostly picks | ar25 8/8 cold | 69 | 28,399 | 562 actions, 258/258 forecasts right, version 0916ai |
| Open 125B model inside Tractatus, mostly picks | cd82 6/6 cold | 43 | 26,249 | 288 actions, 66/66 forecasts right, same version |
| Open 125B model inside Tractatus, mostly picks | tr87 6/6 cold | 43 | 17,439 | 237 actions, 148/148 forecasts right, same version |
| Open 125B model inside Tractatus, mostly picks | bp35 9/9 cold | 57 | 57,025 | 734 actions, 413/417 forecasts right, version 0925jb |
Public-set results are development receipts, not ARC Prize verification. The hidden set is the test, on Kaggle, with the open model offline.
GPT-6 Astra inside the general loop before slicing: one chain per game, no game-specific content. All 25 games cleared, all 183 levels. Five games are reserved: the sliced loop, Tractatus, has never been run or repaired on them, so they are the test at the freeze. ▶ watch is the open model's own cold clear of a game, frames from the run.
| Game | Levels | Status |
|---|---|---|
| ar25 ▶ watch | 8/8 | complete |
| cd82 ▶ watch | 6/6 | complete |
| tr87 ▶ watch | 6/6 | complete |
| bp35 ▶ watch | 9/9 | complete |
| su15 | 9/9 | complete |
| sk48 | 8/8 | complete |
| lp85 | 8/8 | complete |
| sb26 | 8/8 | complete |
| s5i5 | 8/8 | complete |
| re86 | 8/8 | complete |
| ka59 | 7/7 | complete |
| g50t | 7/7 | complete |
| ls20 | 7/7 | complete |
| tn36 | 7/7 | complete |
| sc25 | 6/6 | complete |
| cn04 | 6/6 | complete |
| m0r0 | 6/6 | complete |
| dc22 | 6/6 | complete |
| lf52 | 10/10 | complete · reserved |
| r11l | 6/6 | complete · reserved |
| ft09 | 6/6 | complete · reserved |
| sp80 | 6/6 | complete · reserved |
| vc33 | 7/7 | complete · reserved |
| tu93 | 9/9 | complete |
| wa30 | 9/9 | complete |
Only ar25 has a clean token count; the other chains include the map-writing Astra did while it played.